Deploy AI-Driven Data Center Asset Tracking in 5 to 7 Weeks
Incomplete asset data costs hyperscale operators millions in unplanned downtime—build tracking that scales.
In Brief
Bruviti deployment data shows equipment AI goes live in 5-7 weeks, not the multi-quarter timelines teams expect. For data center OEMs standing up installed-base tracking across servers, PDUs, and cooling, that means a connected asset model feeding fault detection and lifecycle workflows in under two months, grounded in real production deployments.
Implementation Challenges
Fragmented Data Sources
BMC telemetry, provisioning systems, and DCIM tools each track different asset attributes. Building a unified view requires parsing multiple vendor-specific formats and reconciling conflicts across systems.
Configuration Drift Detection
Firmware versions, BIOS settings, and RAID configurations change without updating central records. Detecting drift requires continuous polling and comparison logic that's expensive to build from scratch.
Scale and Latency
Tracking millions of servers across distributed facilities demands real-time updates without overloading network or database infrastructure. Custom implementations often fail at hyperscale volumes.
Implementation Architecture
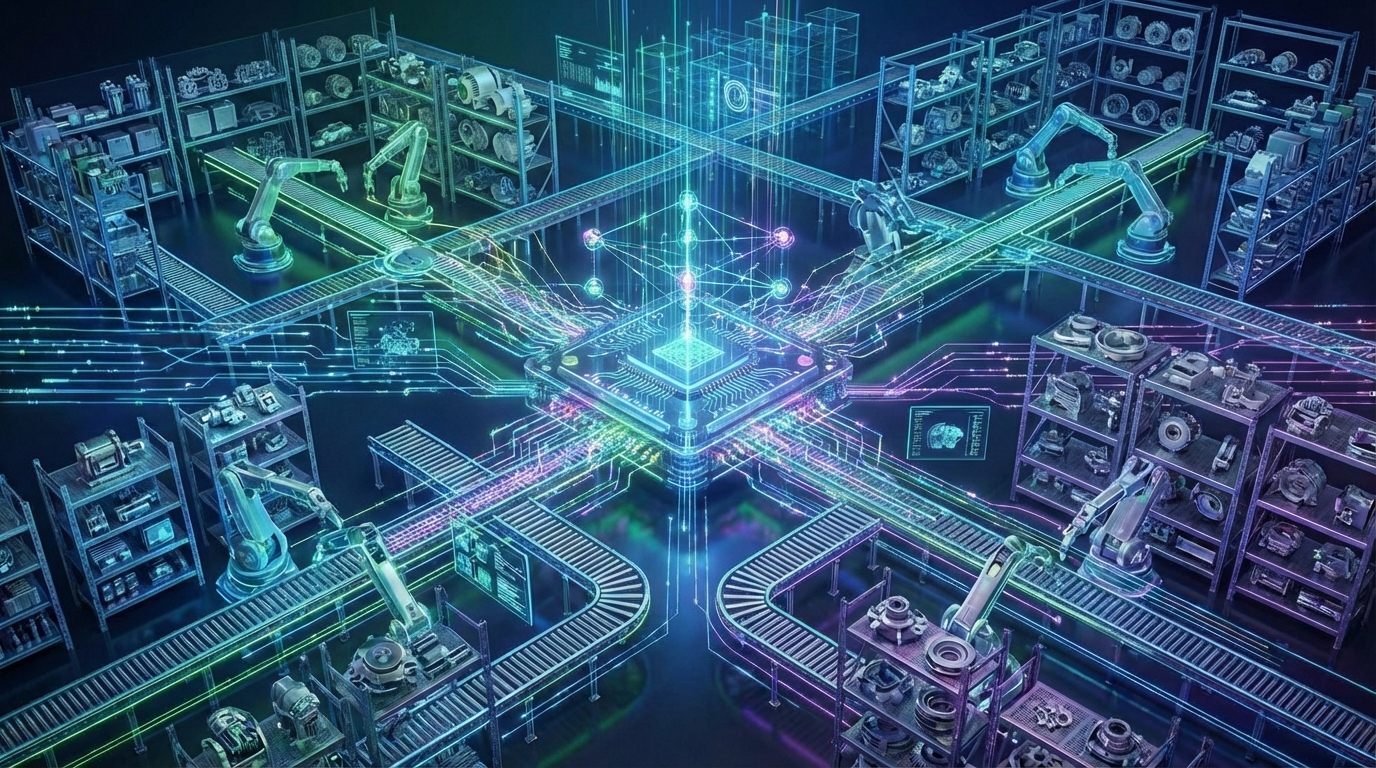
Bruviti's asset tracking APIs provide a headless integration layer between hardware telemetry sources and your existing asset registry. The Python SDK consumes BMC/IPMI streams, normalizes vendor-specific data formats, and exposes a unified schema for configuration state. You write custom lifecycle rules in Python—no proprietary scripting languages or vendor-specific plugins.
The platform handles the heavy lifting: telemetry ingestion at scale, conflict resolution when multiple sources report different states, and incremental updates to minimize network overhead. You control data ownership—export to your data lake, integrate with SAP or Oracle, or build custom dashboards without extracting data through vendor portals. Anti-lock-in by design.
Technical Advantages
- +
API-first design integrates with existing CMDB and DCIM tools in days, not quarters.
- +
Python SDK processes 10K+ asset updates per second without custom infrastructure.
- +
Headless architecture avoids UI lock-in; you own integration and data flows.
See It In Action
Digital Twin Quality Monitoring
Build virtual models of server fleets that mirror real-time BMC telemetry, enabling proactive maintenance before thermal or power anomalies cause outages.
Connected Data Fault Detection
Analyze IoT streams from PDUs, cooling systems, and compute nodes to identify correlated failures across racks and predict cascading issues.
Remaining Useful Life Prediction
Estimate when SSDs, DIMMs, and power supplies will fail based on usage patterns, enabling planned maintenance windows that avoid customer-facing downtime.
Data Center Implementation
Integration Points
Data center OEMs manage asset complexity across compute (blade servers, rack servers), storage (SAN arrays, NAS appliances, HCI clusters), and infrastructure (UPS units, PDUs, cooling systems). Each product line generates telemetry through different protocols—BMC/IPMI for servers, SNMP for network-attached storage, proprietary APIs for cooling equipment.
The asset tracking API normalizes these streams into a unified configuration model. Firmware versions, BIOS settings, RAID states, and thermal profiles become queryable attributes regardless of underlying hardware vendor. Custom Python scripts trigger lifecycle actions—flag servers nearing EOL, identify upgrade candidates for new firmware, or surface configuration inconsistencies across redundant systems.
Implementation Roadmap
- +
Start with high-value compute SKUs to prove ROI before expanding to storage and infrastructure.
- +
Connect BMC/IPMI feeds first; they provide richest telemetry with minimal integration effort.
- +
Track configuration compliance rates weekly; 90% coverage within 60 days proves value to leadership.